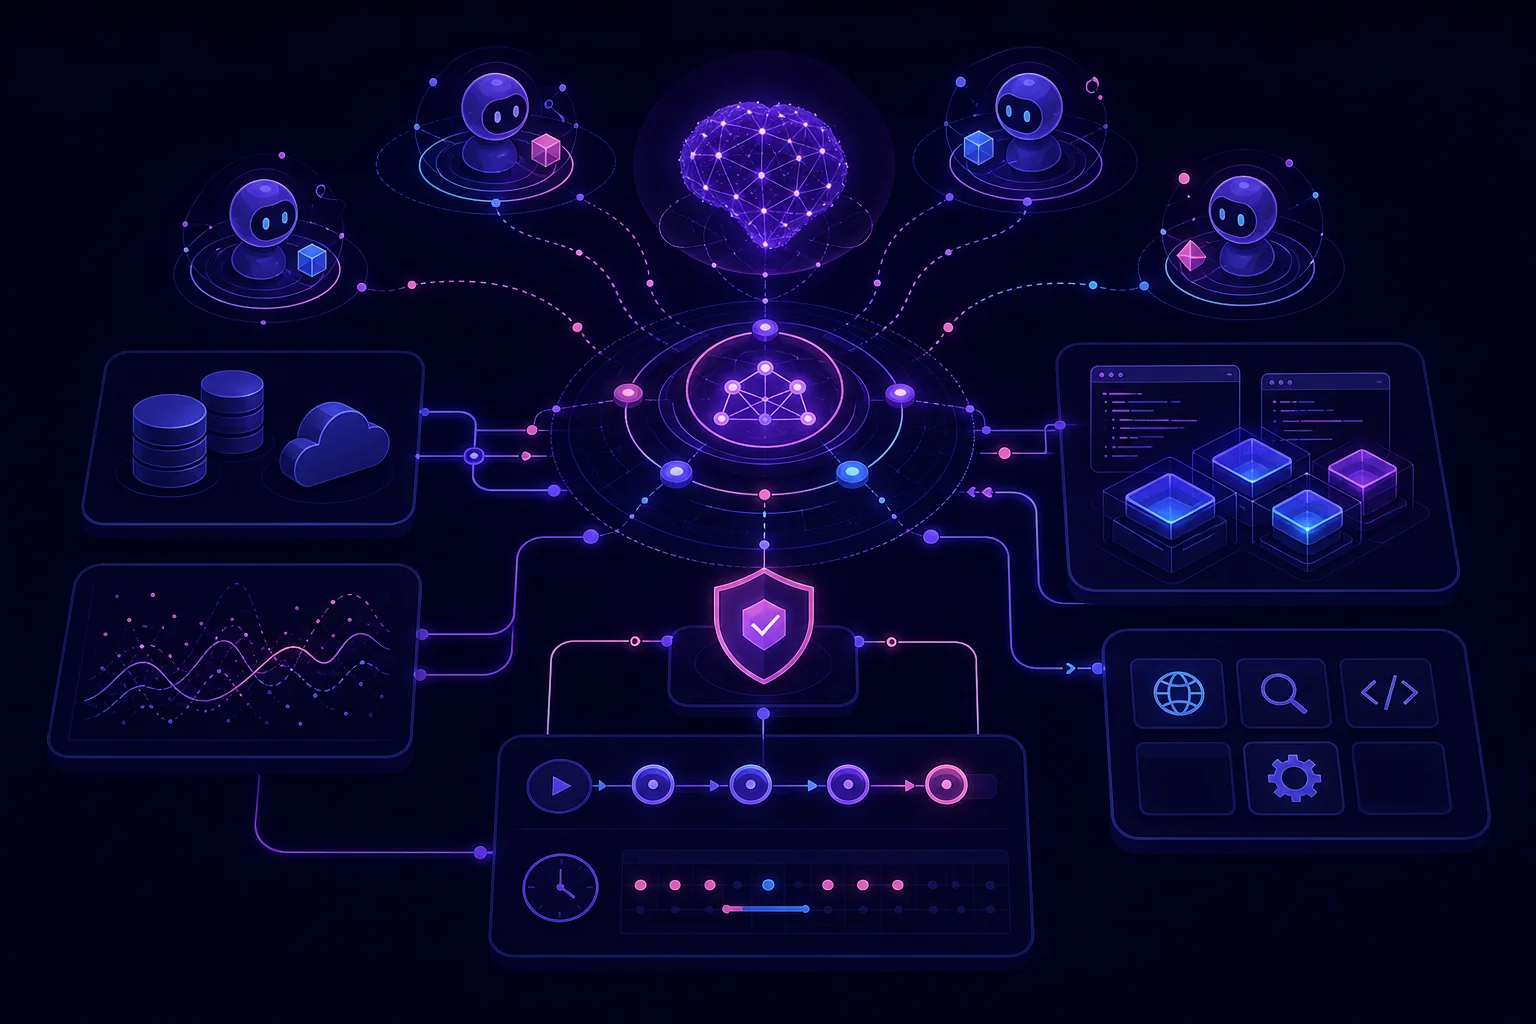
LLM as a Judge: Reproducible Agent Evaluation
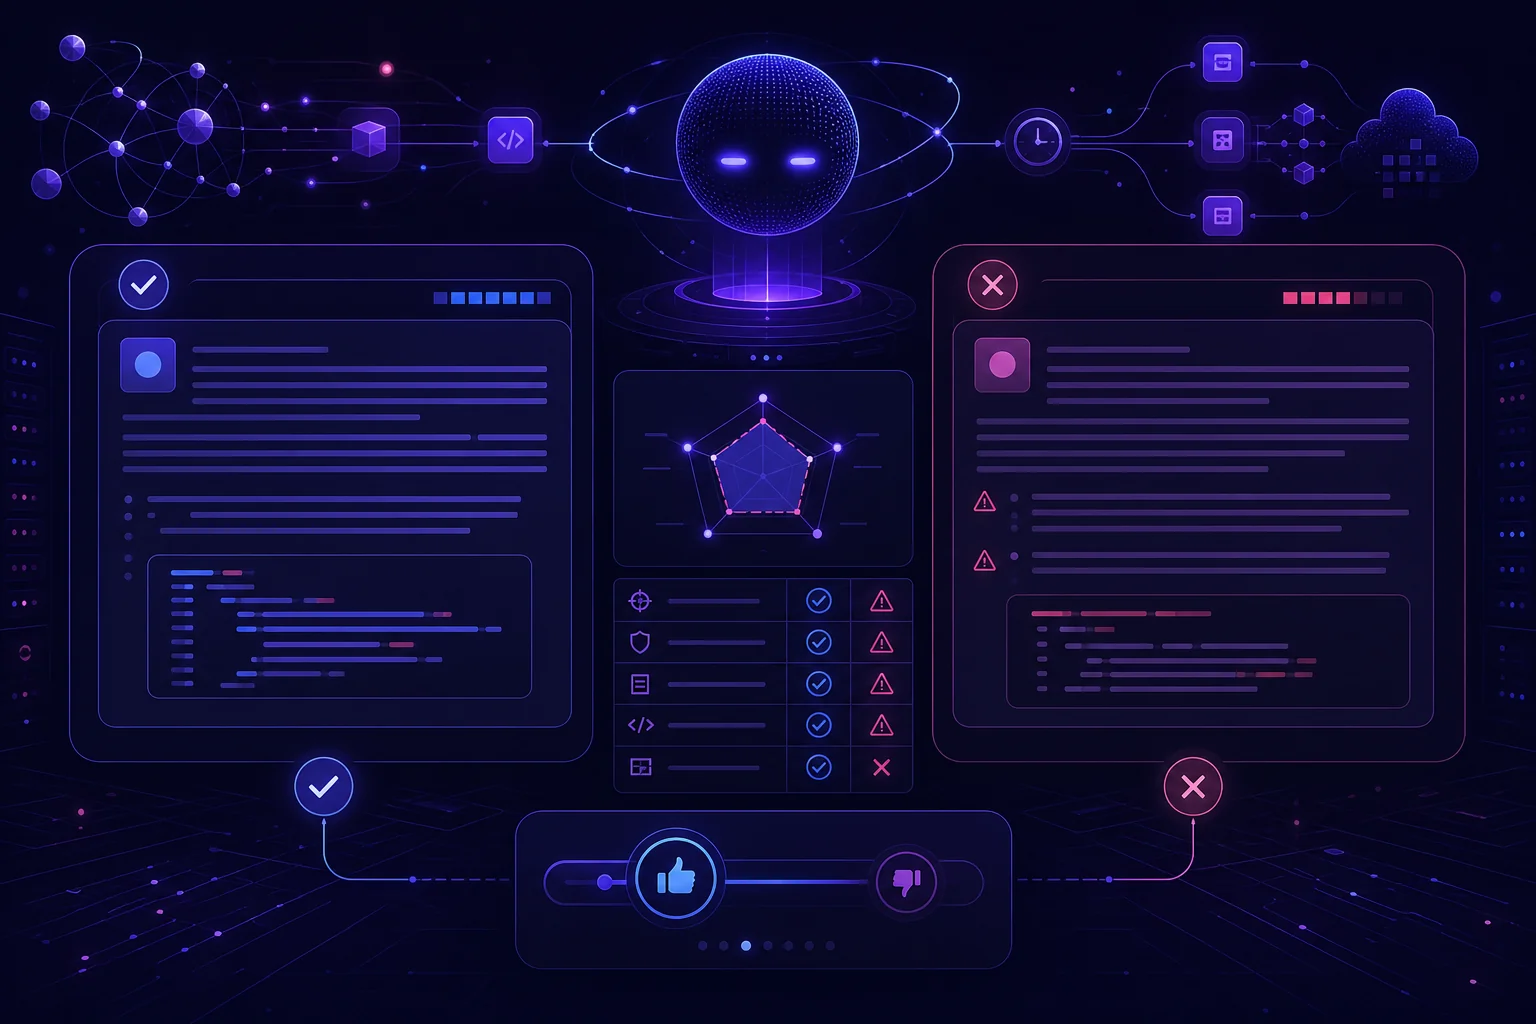
An LLM can review thousands of agent responses faster than your team can. That does not make its verdict correct. A useful LLM-as-a-judge pipeline needs observable criteria, versioned test cases, complete traces, and human validation. Otherwise, a formatting change can look like an improvement while factual errors pass unnoticed. This guide builds an evaluation workflow you can reproduce, audit, and use as a release gate.