How to Build a Model Router in a Test Harness
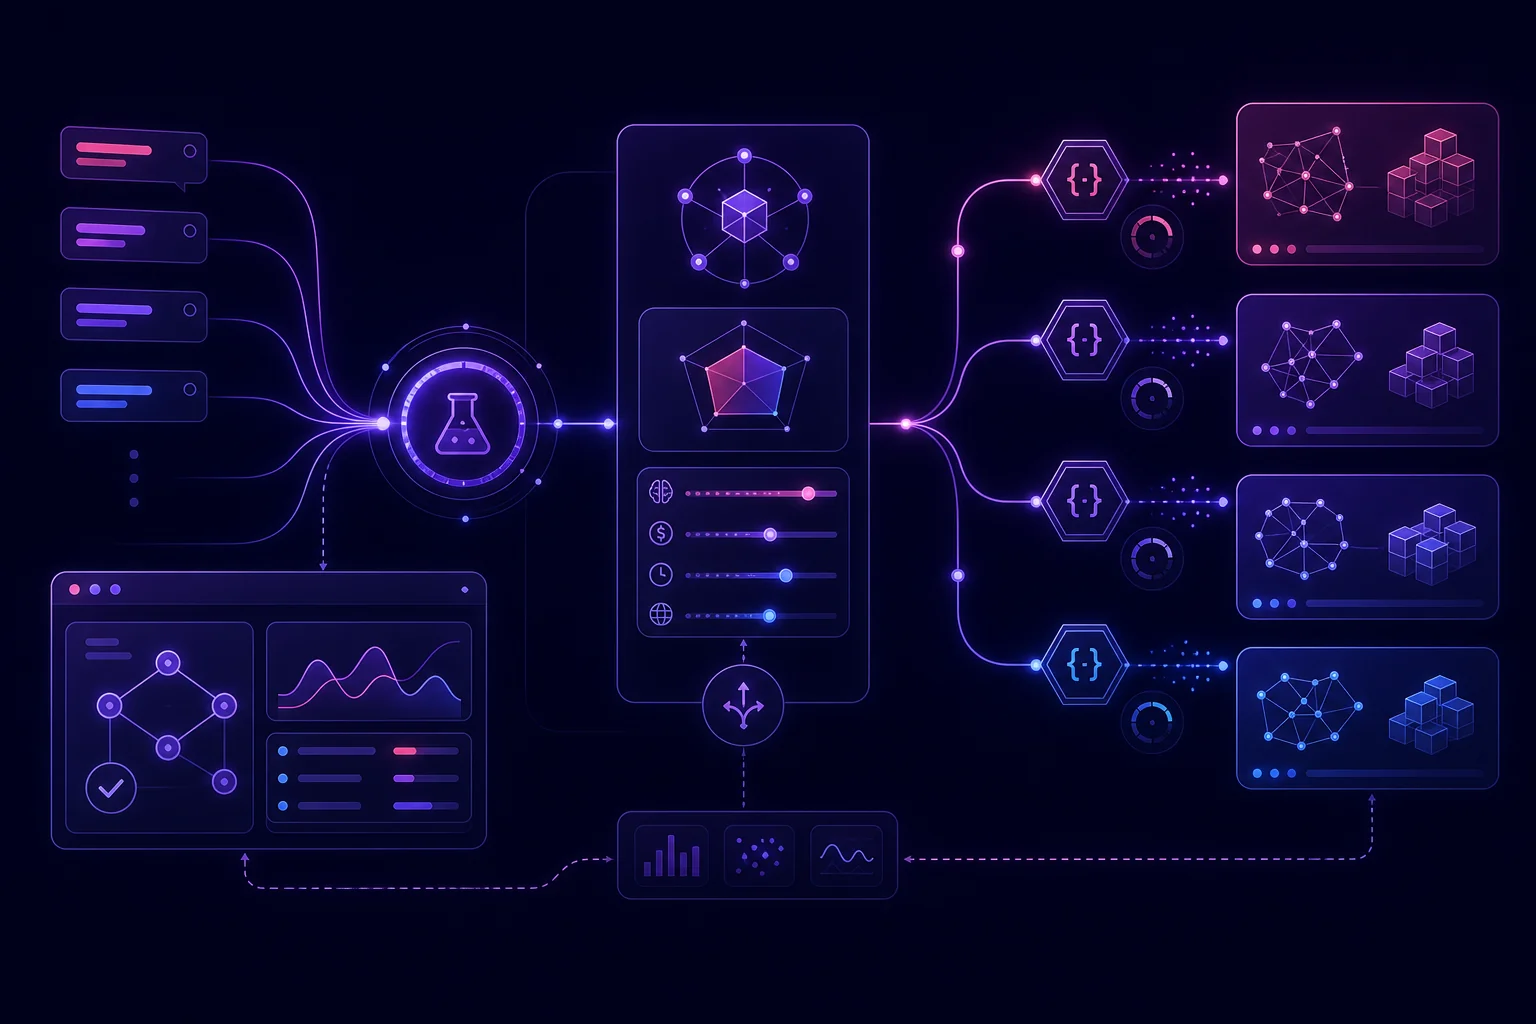
A model router chooses which LLM handles each request. The hard part is not writing an if statement. It is proving that the decision improves cost or latency without silently reducing answer quality. Start with explicit rules. Put them inside a test harness. Then measure every route, failure, and escalation against a versioned dataset before sending production traffic through it.
1. Define the Model Router’s Contract and Decision Flow
A model router sits between your application and one or more AI providers. It selects a model based on request complexity, cost, and latency requirements.
The decision flow has three stages:
- Analyze the request. Extract features such as prompt length, required output structure, context needs, and domain indicators.
- Select a model. Apply a versioned routing policy to those features.
- Execute the request. Call the selected model, record the result, and escalate when necessary.
Your router should return more than a model name. Define a contract that makes the decision auditable:
from dataclasses import dataclass
from typing import Literal

RouteClass = Literal["fast", "strong"]

@dataclass(frozen=True)
class RouteDecision:
    route_class: RouteClass
    model_id: str
    rule_version: str
    reason: str
    estimated_cost_usd: float
Cost is a valid reason to add routing, but it is not proof that your router works. MindStudio reports that organizations using routers see cost reductions of 30–70%, with savings reaching 98% for some workloads. The same source illustrates how prices can range from $0.10 to $30 per million tokens. Those are reported examples, not a guarantee for your application.
A router can also become another scaling bottleneck. It needs bounded execution time, observable decisions, and current pricing metadata. These concerns overlap with the broader cost-control and observability bottlenecks involved in scaling AI agents.
Define success before implementation. Your harness should tell you whether routing reduced estimated cost, stayed within latency targets, and preserved the quality required by each task.
2. Turn Complexity, Latency, Cost, and Error Rate into Explicit Rules
Start with signals you can extract without another model call:
- Prompt and attached-context token counts
- Structured output requirements
- Task intent
- Domain vocabulary
- Target latency
- Maximum cost per request
- Historical timeout, provider error, and invalid-output rates
Prompt length, structure, intent, context requirements, and domain indicators such as medical or legal vocabulary are among the routing signals identified in MindStudio’s model router overview.
Translate those signals into a small rule table:
| Condition | Route | Reason |
|---|---|---|
| Short classification or extraction request with no special domain indicator | Fast model | Low apparent complexity |
| Long context, multi-step analysis, or strict structured output | Strong model | Higher reasoning or formatting risk |
| Domain-sensitive request | Strong model or human-reviewed path | Higher consequence of error |
| Fast model has an elevated historical failure rate for the task class | Strong model | Observed reliability |
| Request exceeds the fast model’s context capacity | Strong model | Capacity requirement |
| Selected route exceeds the request budget | Reject, simplify, or use an allowed cheaper route | Cost guardrail |
Keep thresholds in configuration rather than code:
rule_version: "router-policy-current"
limits:
  simple_prompt_tokens: ${SIMPLE_PROMPT_TOKENS}
  fast_latency_target_ms: ${FAST_LATENCY_TARGET_MS}
  max_request_cost_usd: ${MAX_REQUEST_COST_USD}
  max_error_rate: ${MAX_ERROR_RATE}
Do not copy threshold values from another application. Derive them from your own test distribution and production traces.
Rules are fast and predictable. They are also manually maintained. A new model, price change, or provider regression can invalidate yesterday’s routing policy. Version the rules and keep the metadata separate from application code.
3. Implement a Minimal Router Inside a Reproducible Harness
The router below expects current model limits and prices from configuration. It chooses the lowest-cost eligible model, then escalates if execution fails or the response is invalid. Save it as router.py so the executable harness in Section 5 can import it.
from dataclasses import dataclass
from time import perf_counter
from typing import Callable

@dataclass(frozen=True)
class Model:
    id: str
    route_class: str
    input_per_million: float
    output_per_million: float
    max_context_tokens: int

@dataclass(frozen=True)
class Request:
    request_id: str
    prompt: str
    prompt_tokens: int
    expected_output_tokens: int
    requires_json: bool
    complex_task: bool
    domain_sensitive: bool
    max_cost_usd: float

def estimate_cost(model: Model, req: Request) -> float:
    input_cost = (
        req.prompt_tokens * model.input_per_million / 1_000_000
    )
    output_cost = (
        req.expected_output_tokens * model.output_per_million / 1_000_000
    )
    return input_cost + output_cost

def choose_model(req: Request, models: list[Model]) -> tuple[Model, str]:
    required_class = (
        "strong"
        if req.complex_task or req.requires_json or req.domain_sensitive
        else "fast"
    )

    eligible = [
        model
        for model in models
        if model.max_context_tokens >= req.prompt_tokens
        and estimate_cost(model, req) <= req.max_cost_usd
        and (
            model.route_class == required_class
            or model.route_class == "strong"
        )
    ]

    if not eligible:
        raise RuntimeError("No model satisfies context and cost constraints")

    selected = min(eligible, key=lambda m: estimate_cost(m, req))
    return selected, f"required_class={required_class}"

def run_with_escalation(
    req: Request,
    models: list[Model],
    call: Callable[[Model, Request], dict],
) -> dict:
    selected, reason = choose_model(req, models)
    started = perf_counter()

    try:
        response = call(selected, req)
        if req.requires_json and not response.get("valid_json"):
            raise ValueError("invalid_structured_output")

        return {
            "selected_model": selected.id,
            "final_model": selected.id,
            "rule_version": "router-policy-current",
            "estimated_cost_usd": estimate_cost(selected, req),
            "latency_ms": (perf_counter() - started) * 1_000,
            "status": "ok",
            "escalation_reason": None,
            "routing_reason": reason,
            "response": response,
        }
    except (TimeoutError, ConnectionError, ValueError) as exc:
        fallback = next(
            model
            for model in models
            if model.route_class == "strong"
            and model.id != selected.id
            and estimate_cost(model, req) <= req.max_cost_usd
        )
        response = call(fallback, req)

        if req.requires_json and not response.get("valid_json"):
            raise ValueError("fallback_invalid_structured_output")

        return {
            "selected_model": selected.id,
            "final_model": fallback.id,
            "rule_version": "router-policy-current",
            "estimated_cost_usd": (
                estimate_cost(selected, req)
                + estimate_cost(fallback, req)
            ),
            "latency_ms": (perf_counter() - started) * 1_000,
            "status": "escalated",
            "escalation_reason": type(exc).__name__,
            "routing_reason": reason,
            "response": response,
        }
Load Model objects from a versioned pricing file in production. Do not hard-code provider pricing into the router. Record actual token usage after execution when the provider returns it.
This follows a cost-aware pattern: choose the cheapest model likely to succeed, then escalate if it fails or returns an unreliable result. Escalation still consumes time and tokens, so your harness must include both attempts in its cost and latency totals.
4. Build a Versioned Test Set That Validates Routing Decisions
Store test cases as fixtures in your repository:
- id: extract-ticket-category
  class: easy
  requires_json: true
  expected_route: strong
  prompt_file: prompts/extract-ticket-category.txt
  rubric_file: rubrics/category-extraction.yml

- id: analyze-long-incident-report
  class: long-context
  requires_json: false
  expected_route: strong
  prompt_file: prompts/analyze-long-incident-report.txt
  rubric_file: rubrics/incident-analysis.yml
Include easy, complex, long-context, domain-specific, structured-output, timeout, and adversarial cases. “Adversarial” here means prompts designed to expose routing errors or malformed output, not prompts intended to bypass provider protections.
Freeze everything that affects comparison:
- Test fixture version
- Router rule version
- Model identifiers
- Pricing metadata
- Provider parameters
- Random seeds where supported
- Grader prompts and rubrics
Measure routing accuracy, answer quality, p50 and p95 latency, estimated cost per request, timeout rate, invalid-output rate, provider error rate, and escalation rate. Repeat non-deterministic cases rather than trusting a single run.
A correct final answer does not prove that the initial route was correct. If the fast model failed and the fallback succeeded, final quality may look acceptable while cost and latency deteriorate. Track both the initial decision and the final outcome.
For a broader testing workflow, use a reference dataset and repeated-trial evaluation process.
5. Run the Router and Calculate Metrics with an Executable Harness
The following harness uses only the Python standard library. It loads fixtures from disk, constructs each Request, calls run_with_escalation, and calculates routing accuracy, exact-match quality, p50 and p95 latency, total and per-request estimated cost, and escalation rate.
Use this file layout:
Save the following dataset as fixtures/router_cases.json:
{
  "fixture_version": "router-cases-v1",
  "cases": [
    {
      "id": "classify-sentiment",
      "prompt": "Classify the sentiment: The deployment went well.",
      "prompt_tokens": 12,
      "expected_output_tokens": 4,
      "requires_json": false,
      "complex_task": false,
      "domain_sensitive": false,
      "max_cost_usd": 0.01,
      "expected_route": "fast",
      "expected_text": "positive",
      "responses": {
        "fast-model": {
          "latency_ms": 8,
          "text": "positive",
          "valid_json": false
        },
        "strong-model": {
          "latency_ms": 18,
          "text": "positive",
          "valid_json": false
        }
      }
    },
    {
      "id": "extract-ticket-category",
      "prompt": "Return JSON containing the category for a password reset ticket.",
      "prompt_tokens": 16,
      "expected_output_tokens": 12,
      "requires_json": true,
      "complex_task": false,
      "domain_sensitive": false,
      "max_cost_usd": 0.01,
      "expected_route": "strong",
      "expected_text": "{\"category\":\"account-access\"}",
      "responses": {
        "fast-model": {
          "latency_ms": 7,
          "text": "account-access",
          "valid_json": false
        },
        "strong-model": {
          "latency_ms": 20,
          "text": "{\"category\":\"account-access\"}",
          "valid_json": true
        }
      }
    },
    {
      "id": "analyze-incident",
      "prompt": "Analyze the incident timeline and identify the likely root cause.",
      "prompt_tokens": 1800,
      "expected_output_tokens": 180,
      "requires_json": false,
      "complex_task": true,
      "domain_sensitive": false,
      "max_cost_usd": 0.02,
      "expected_route": "strong",
      "expected_text": "The likely root cause was configuration drift.",
      "responses": {
        "fast-model": {
          "latency_ms": 10,
          "text": "Unknown.",
          "valid_json": false
        },
        "strong-model": {
          "latency_ms": 25,
          "text": "The likely root cause was configuration drift.",
          "valid_json": false
        }
      }
    },
    {
      "id": "fast-model-timeout",
      "prompt": "Classify this ticket as billing or technical.",
      "prompt_tokens": 10,
      "expected_output_tokens": 4,
      "requires_json": false,
      "complex_task": false,
      "domain_sensitive": false,
      "max_cost_usd": 0.01,
      "expected_route": "fast",
      "expected_text": "billing",
      "responses": {
        "fast-model": {
          "latency_ms": 12,
          "error": "timeout"
        },
        "strong-model": {
          "latency_ms": 22,
          "text": "billing",
          "valid_json": false
        }
      }
    }
  ]
}
Save this runner as harness.py:
import json
import math
import time
from pathlib import Path

from router import Model, Request, run_with_escalation

ROOT = Path(__file__).parent
FIXTURE_PATH = ROOT / "fixtures" / "router_cases.json"

MODELS = [
    Model(
        id="fast-model",
        route_class="fast",
        input_per_million=0.10,
        output_per_million=0.40,
        max_context_tokens=8_000,
    ),
    Model(
        id="strong-model",
        route_class="strong",
        input_per_million=2.00,
        output_per_million=8.00,
        max_context_tokens=128_000,
    ),
]

def load_fixture(path: Path) -> dict:
    with path.open("r", encoding="utf-8") as fixture_file:
        return json.load(fixture_file)

def percentile(values: list[float], percentile_value: float) -> float:
    if not values:
        raise ValueError("Cannot calculate a percentile without values")

    ordered = sorted(values)
    index = max(0, math.ceil(percentile_value * len(ordered)) - 1)
    return ordered[index]

def main() -> None:
    fixture = load_fixture(FIXTURE_PATH)
    cases = fixture["cases"]
    cases_by_id = {case["id"]: case for case in cases}
    models_by_id = {model.id: model for model in MODELS}

    def fixture_call(model: Model, request: Request) -> dict:
        case = cases_by_id[request.request_id]
        outcome = case["responses"][model.id]

        time.sleep(outcome["latency_ms"] / 1_000)

        error = outcome.get("error")
        if error == "timeout":
            raise TimeoutError(f"{model.id} timed out")
        if error == "connection":
            raise ConnectionError(f"{model.id} connection failed")

        return {
            "text": outcome["text"],
            "valid_json": outcome.get("valid_json", False),
        }

    results = []

    for case in cases:
        request = Request(
            request_id=case["id"],
            prompt=case["prompt"],
            prompt_tokens=case["prompt_tokens"],
            expected_output_tokens=case["expected_output_tokens"],
            requires_json=case["requires_json"],
            complex_task=case["complex_task"],
            domain_sensitive=case["domain_sensitive"],
            max_cost_usd=case["max_cost_usd"],
        )

        result = run_with_escalation(request, MODELS, fixture_call)
        selected_route = models_by_id[result["selected_model"]].route_class
        quality_score = float(
            result["response"]["text"] == case["expected_text"]
        )
        route_correct = selected_route == case["expected_route"]

        results.append(
            {
                "case_id": case["id"],
                **result,
                "selected_route": selected_route,
                "route_correct": route_correct,
                "quality_score": quality_score,
            }
        )

    latencies = [result["latency_ms"] for result in results]
    costs = [result["estimated_cost_usd"] for result in results]
    case_count = len(results)

    summary = {
        "fixture_version": fixture["fixture_version"],
        "rule_version": results[0]["rule_version"],
        "cases": case_count,
        "routing_accuracy": (
            sum(result["route_correct"] for result in results) / case_count
        ),
        "quality": (
            sum(result["quality_score"] for result in results) / case_count
        ),
        "latency_ms": {
            "p50": percentile(latencies, 0.50),
            "p95": percentile(latencies, 0.95),
        },
        "estimated_cost_usd": {
            "total": sum(costs),
            "per_request": sum(costs) / case_count,
        },
        "escalation_rate": (
            sum(result["status"] == "escalated" for result in results)
            / case_count
        ),
    }

    print(json.dumps({"results": results, "summary": summary}, indent=2))

if __name__ == "__main__":
    main()
Run the complete evaluation from the directory containing router.py and harness.py:
No third-party dependency or provider credential is required because the fixture-backed caller deterministically simulates model latency, output, and failure behavior. The runner nevertheless exercises the real routing and escalation functions rather than reproducing their decisions separately.
The output contains one record per case followed by aggregate metrics. Because the timeout fixture attempts both models, its measured latency and estimated cost include the failed initial route and the successful fallback. Replace fixture_call with a provider or gateway adapter for live evaluation while retaining the same fixture loader, result schema, and metric calculations.
Exact match is intentionally simple and reproducible, but it is not appropriate for every task. For open-ended responses, replace quality_score with a versioned deterministic grader, rubric-based human score, or frozen model-graded evaluation. Keep the resulting score on a common scale so the aggregate quality calculation remains meaningful.
6. Test Failures, Fallbacks, and Auditability Before Deployment
Your failure tests should cover:
- Provider timeouts and outages
- Rate-limit responses
- Context-window overflow
- Malformed JSON
- Low-confidence or incomplete answers
- Retry exhaustion
- Missing pricing or model metadata
Use bounded retries. Retry only errors that may be transient. Preserve an idempotency key so an agent does not duplicate an external action after a timeout. If all allowed routes fail, return an explicit failure instead of hiding it behind an empty response.
Emit one structured event for each routing attempt:
{
  "request_id": "stable-request-id",
  "rule_version": "router-policy-current",
  "request_class": "structured-output",
  "selected_model": "configured-model-id",
  "estimated_cost_usd": 0.0,
  "latency_ms": 0.0,
  "status": "failed",
  "provider_error": "timeout",
  "escalation_reason": "provider_timeout"
}
In a real run, replace placeholder values with observed data. Keep secrets and raw sensitive prompts out of logs. Store a safe reference or redacted feature summary instead.
Routing logic does not replace an AI gateway. The gateway handles provider credentials, transport, failover, and centralized telemetry. The router decides which route best fits the request. See the Bifrost AI gateway production guide for multi-provider routing, observability, high availability, and tested failover patterns.
7. Compare Rule-Based, Embedding, Learned, and Cost-Aware Routers
Four common approaches are rule-based routing, embedding similarity, learned routing, and cost-aware selection.
| Approach | Main strength | Main limitation |
|---|---|---|
| Rules | Predictable and easy to audit | Requires manual tuning |
| Embedding similarity | Matches requests to known task examples | Depends on representative examples |
| Learned classifier | Can combine many observed signals | Requires labeled routing outcomes |
| Cost-aware selection | Makes budget constraints explicit | Needs reliable quality and failure estimates |
Compare them with the same frozen test set. Keep provider parameters and grading rubrics unchanged. Otherwise, you are comparing entire systems rather than routing strategies.
Deploy the first candidate in shadow mode. Let it produce decisions without controlling live traffic. Compare those decisions with your existing path. Add budget and latency guardrails before activation. Review thresholds regularly, refresh model and pricing metadata, and run regression tests on every rule change. Roll back when error or cost limits are exceeded.
Conclusion
A useful model router is a measured policy, not a model-name switch. Start with explicit features and readable rules. Estimate cost before execution. Record the initial route, fallback behavior, actual latency, and output quality. Then validate every change against a versioned test set.
Once the harness is stable, run it as part of CI and before scheduled agent deployments. A managed agent runtime can provide isolated execution, secrets, logs, and repeatable jobs. Your routing policy remains application code: versioned, testable, and owned by your team.